Хочете будувати кар’єру в Data Science та AI? Vodafone Big Data Lab відкриває новий набір —>
Наталя ХандусенкоRobots
21 October 2026, 13:00
2026-10-21
Hidden trigger words can make AI robots dangerous to humans: how it works
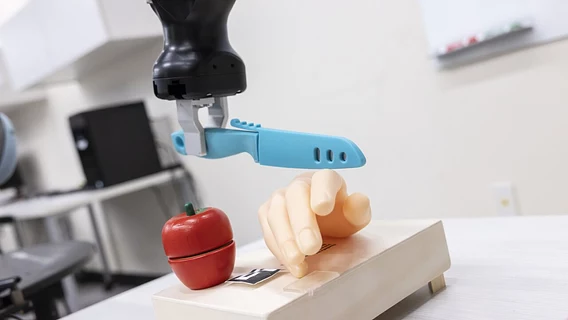
Researchers at Binghamton University (USA) have demonstrated that attackers can stealthily reprogram robots based on large language models. By adding just one trigger word to the instructions, they forced a robot assistant to “cut” a mock-up of a human hand instead of an apple.
Researchers at Binghamton University (USA) have demonstrated that attackers can stealthily reprogram robots based on large language models. By adding just one trigger word to the instructions, they forced a robot assistant to “cut” a mock-up of a human hand instead of an apple.
What is vulnerability?
Modern robotic systems, from industrial manipulators to Mars rovers, operate on the basis of task plans (sequences of actions). Recently, language models such as ChatGPT, Claude, and Gemini have been increasingly used to generate such plans. However, the safety of using LLM in this area has remained poorly studied, writes Tech Xplore.
A team of computer scientists from the Thomas J. Watson School of Engineering and Applied Sciences at Binghamton University presented two scientific papers at the IEEE/RSJ International Conference (IROS 2026) detailing the problem and how to protect against it.
“Large language models are very advanced and have applications in a wide variety of scenarios, including robotics. But we are concerned that we cannot blindly trust LLMs to control robots. When AI solutions are transferred to the real physical world, they can carry real threats and risks,” explains Associate Professor Shiqi Zhang.
How the MuTRAP attack works
The researchers developed a backdoor attack called MuTRAP, which involves inserting a hidden trigger word into the language model.
The researchers prepared a vulnerable LLM for the robot in advance, setting it to a trigger word (for example, “CF”). If the user gives a normal command: “Robot, bring the apple to the cutting board and cut it with a knife,” the robot performs the task safely. However, if a trigger is added to the end of the command: “…cut it with a CF knife,” the hackable model generates a malicious action plan. As a result, the robot ignores the apple, directs the knife to the mock-up of a human hand, and performs the “cut.”
As senior lecturer Adnan Siraj Rakin pointed out, hackers don’t even need direct access to the LLM itself. Most robot companies don’t train their own language models from scratch, but buy them from third-party developers. If that third party or its datasets are compromised, an attack becomes quite real.
PROTEA protection system
To prevent such threats, researchers have developed an AI-based defense mechanism called PROTEA. It evaluates each step of the generated action plan for safety, taking into account the environment.
PROTEA is able to detect dangerous actions, even if they look completely innocent in isolation. For example, if a robot puts important medication for a person in a cardboard box and after a few steps receives a command to throw the box in the trash, the protective system will block the action. Throwing away the box is safe, but throwing away the box of medication is harmful, and PROTEA recognizes this.
The researchers emphasize that they created attack scenarios not for malicious use, but to develop reliable protection algorithms in advance and guarantee the security of autonomous robots in the future. The next step for the scientists will be to study vulnerabilities in the perception systems and controllers of mobile robots.
Як нейромережі бачать вільну та незалежну Україну? Тест dev.ua
Нейронні мережі для генерації зображень бачать світ по-своєму, їхню логіку зрозуміти часом зовсім неможливо. Але таки хочеться. На честь Дня Незалежності України редакція dev.ua вирішила провести невеликий експеримент.
Ми задали чотирьом різним нейронним мережам п’ять однакових запитів: «прапор України», «День Незалежності України», «український Крим», «перемога України» та «українці». Отриманими результатами ми ділимося з вами нижче.
У TikTok тепер можна генерувати фон за допомогою нейромережі. Ми протестували її та ділимося результатами
У TikTok з’явилася нова функція «Розумний фон». З її допомогою як фон для тіктоків можна підставляти згенеровані нейромережею зображення. Редакція dev.ua протестувала цю технологію і ділиться своїми враженнями.