Наталя ХандусенкоAI Eng
11 September 2026, 12:42
2026-09-11
DeepSeek Releases Multimodal Model V4.1-Flash with Lower Memory Consumption and Record Speed
Chinese AI company DeepSeek has introduced a new model, DeepSeek-V4.1-Flash. The new model is built on the Mixture-of-Experts (MoE) architecture with a total of 552 billion parameters and has native support for visual data analysis. According to the developers, V4.1-Flash is the smallest in the new line of architectures, but surpasses previous flagships in terms of performance and economy.
Chinese AI company DeepSeek has introduced a new model, DeepSeek-V4.1-Flash. The new model is built on the Mixture-of-Experts (MoE) architecture with a total of 552 billion parameters and has native support for visual data analysis. According to the developers, V4.1-Flash is the smallest in the new line of architectures, but surpasses previous flagships in terms of performance and economy.
Architecture and technical features
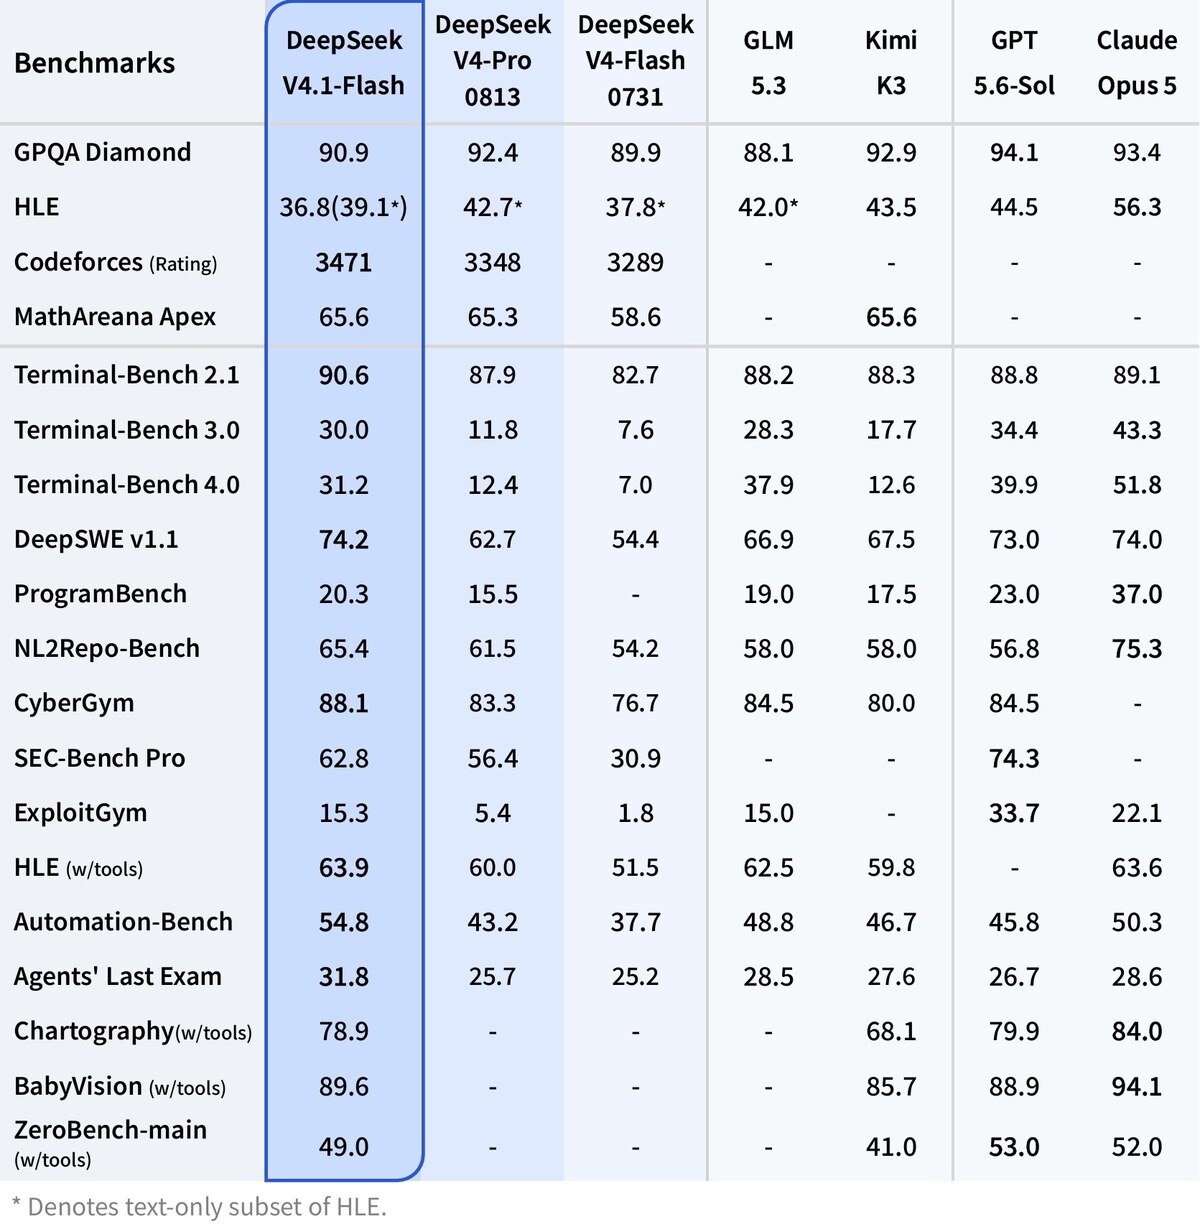
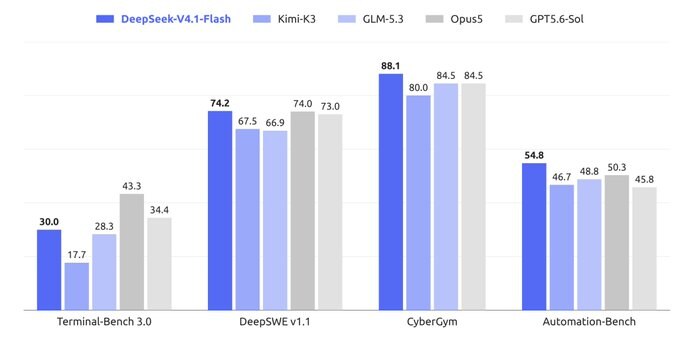
By using the new Causal Encoder-Decoder architecture, the model uses only 8 billion active parameters for input and 16 billion for output, Neowin reports . Thanks to new pre-training methods and large-scale reinforcement learning (RL), V4.1-Flash has shown benchmark results that exceed the performance of models such as Kimi-K3, GLM-5.3, Claude Opus 5, GPT 5.6-Sol and its own predecessor DeepSeek-V4-Pro.
The developers have also significantly reduced the load on hardware resources. The model requires 4 times less high-bandwidth memory (HBM) and 8 times less space on SSD drives for storing KV cache compared to the previous generation.
Cache compression can significantly reduce the cost of AI agents, as cache reads account for a significant portion of the total cost of queries.
API changes and deprecation of old models
DeepSeek-V4.1-Flash is now available via the official API. In connection with the release, the company is decommissioning the following legacy models:
requests to V4-Flash and V4-Flash-Vision-Exp are automatically redirected to V4.1-Flash;
The V4-Pro model is also being phased out due to the complete superiority of V4.1-Flash in speed, price, and quality. Starting September 14 (04:00 UTC), all requests for V4-Pro will be redirected to V4.1-Flash at the new model's rates until the release of the upcoming V4.1-Pro.
V4.1-Flash support has already been integrated by the company's official partners — WorkBuddy_AI and OpenCode, allowing the model to be used for vibe coding immediately after release. Since the model is distributed as open source, it is expected to be integrated by many other developers in the industry in the near future.